Ali Vosoughi

University of Rochester | Dissertation complete
Vision-language models and multimodal LLMs: video understanding, multimodal reasoning and RL post-training, plus audio-language models.
Ali Vosoughi builds vision-language models that reason over images and video, and the tests that check whether they did. His work spans video understanding, multimodal reasoning and evaluation, RL post-training with verifiable rewards, and audio-language models, across four industry labs,
Apple,
Microsoft Research,
Smule, and
Bosch AI Research,
and federally supported programs including
DARPA, NIH, NSF, and NNSA. His methods include post-training of multimodal models with SFT, DPO, and reinforcement learning, and evaluation using significance testing, bootstrap confidence intervals, and human-in-the-loop protocols, built in Python and PyTorch. He writes the software as well as the papers, including production code.
AAAI 2026 Best Demonstration Award Runner-up
co-inventor, US patent application US 2025/0124292 A1
COLM · NeurIPS · NAACL · ACM MM · ICASSP
co-inventor, US patent application US 2025/0124292 A1
COLM · NeurIPS · NAACL · ACM MM · ICASSP
📧 ali.vosoughi@rochester.edu
📍 CS Department, Wegmans Hall 3211
🍎 Apple
Machine Learning Intern
A multi-agent multimodal system
A multi-agent multimodal system
🎵 Smule AI
Research Scientist Intern
Spatial Generation
Spatial Generation
🏢 Microsoft Research
Research Intern
Video/Audio LLM and Video Understanding
Video/Audio LLM and Video Understanding
🚗 Bosch AI Research
Research Intern
LLM and Counterfactual Learning
LLM and Counterfactual Learning
🛡️ DARPA PTG
Graduate Researcher
Autonomous Multimodal Perception and AR
Autonomous Multimodal Perception and AR
🎓 University of Rochester
Graduate Research Assistant, 2019 to present
Multimodal AI across DARPA, NIH, NSF, and NNSA programs
Advisors: Axel Wismueller and Chenliang Xu
Multimodal AI across DARPA, NIH, NSF, and NNSA programs
Advisors: Axel Wismueller and Chenliang Xu
AAAI 2026 Best Demonstration Award Runner-up
Caption Anything in Video (Spatiotemporal Multimodal Prompting)
Caption Anything in Video (Spatiotemporal Multimodal Prompting)
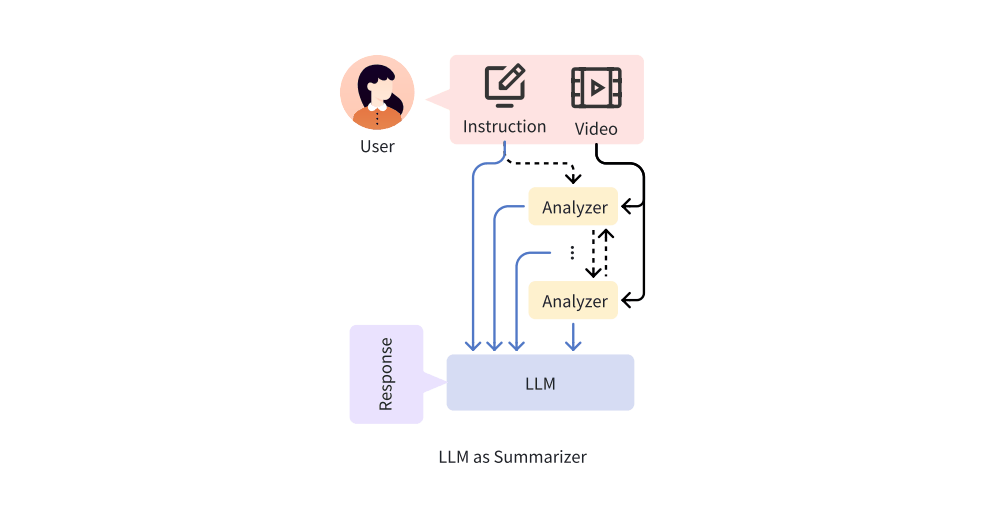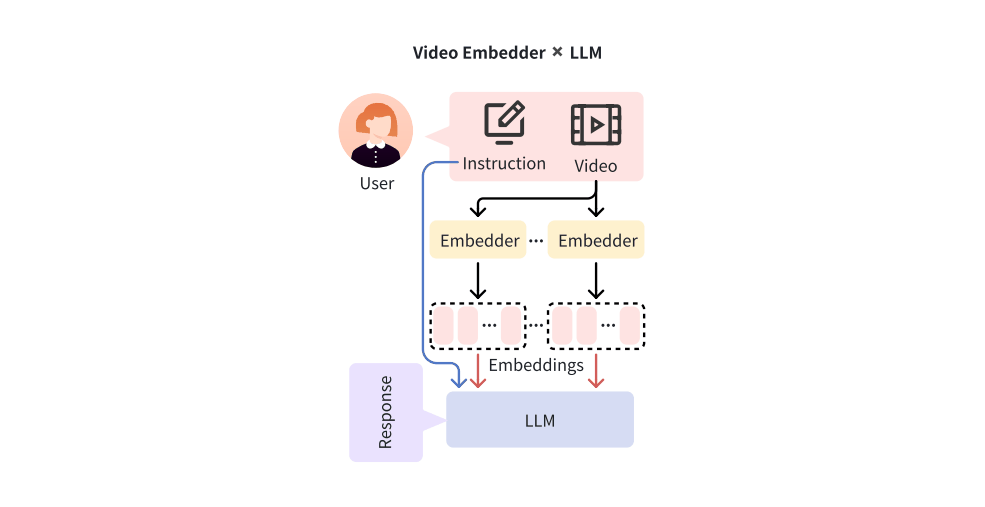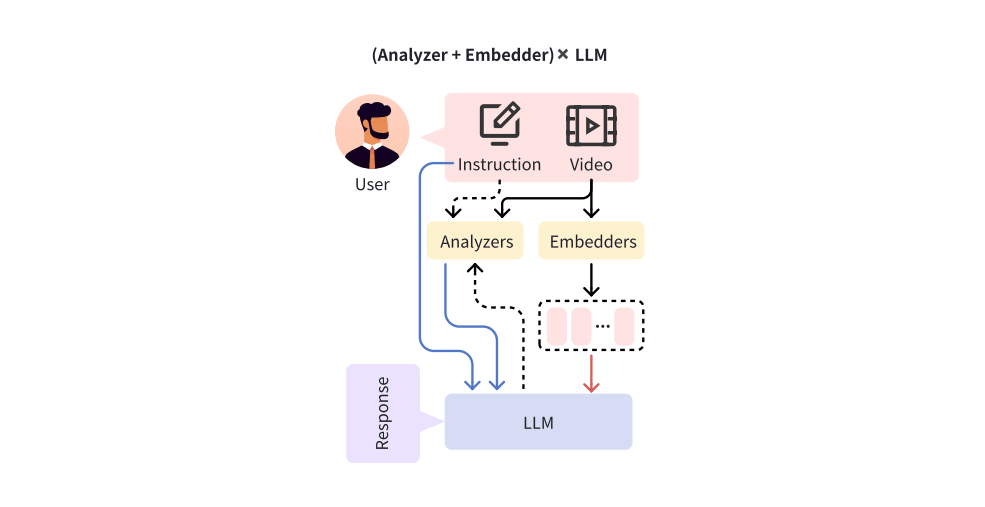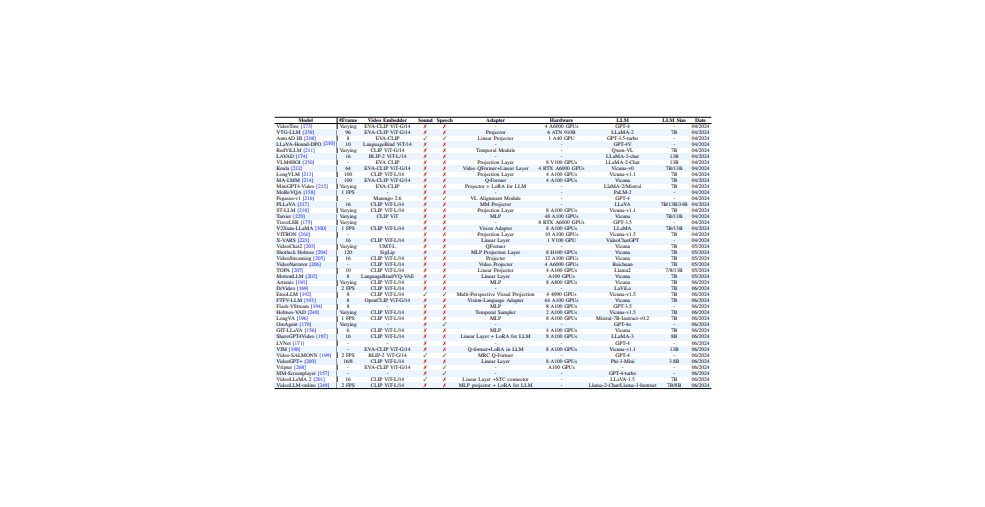
Video Understanding with LLMs
Comprehensive survey (IEEE TCSVT 2025)
Comprehensive survey (IEEE TCSVT 2025)
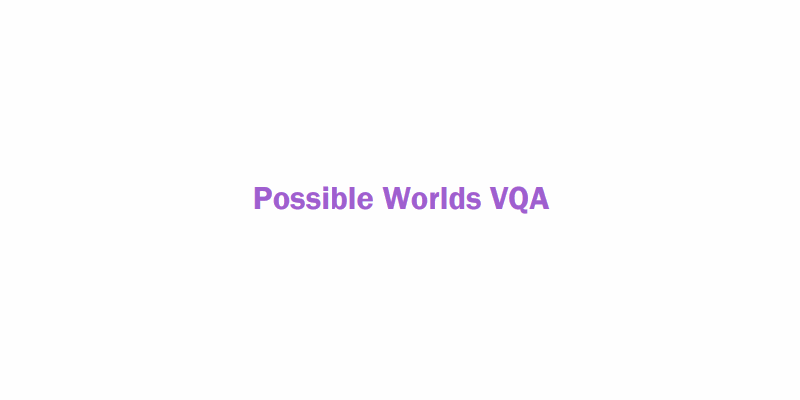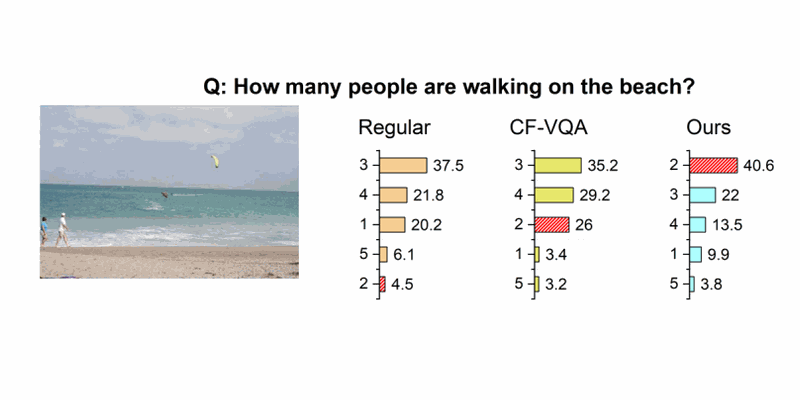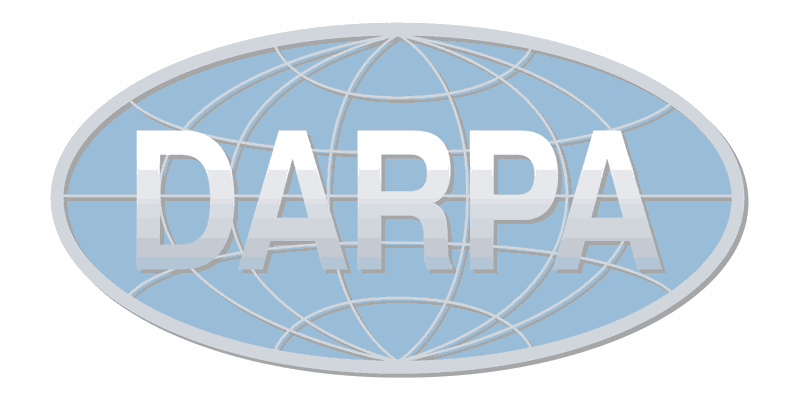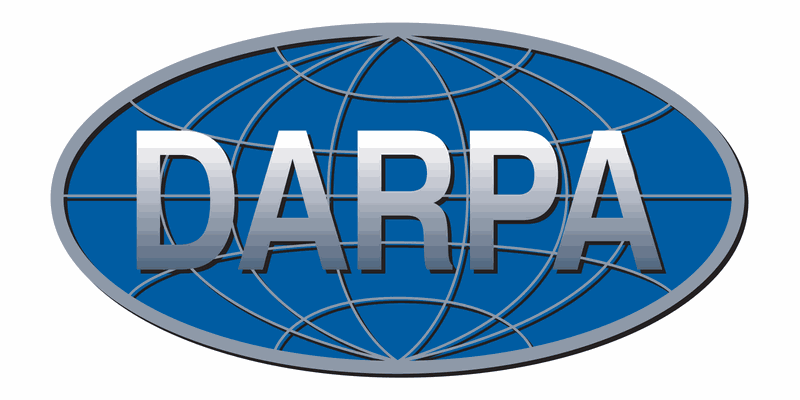
PW-VQA
Causal debiasing for visual question answering (IEEE TMM 2024)
Causal debiasing for visual question answering (IEEE TMM 2024)
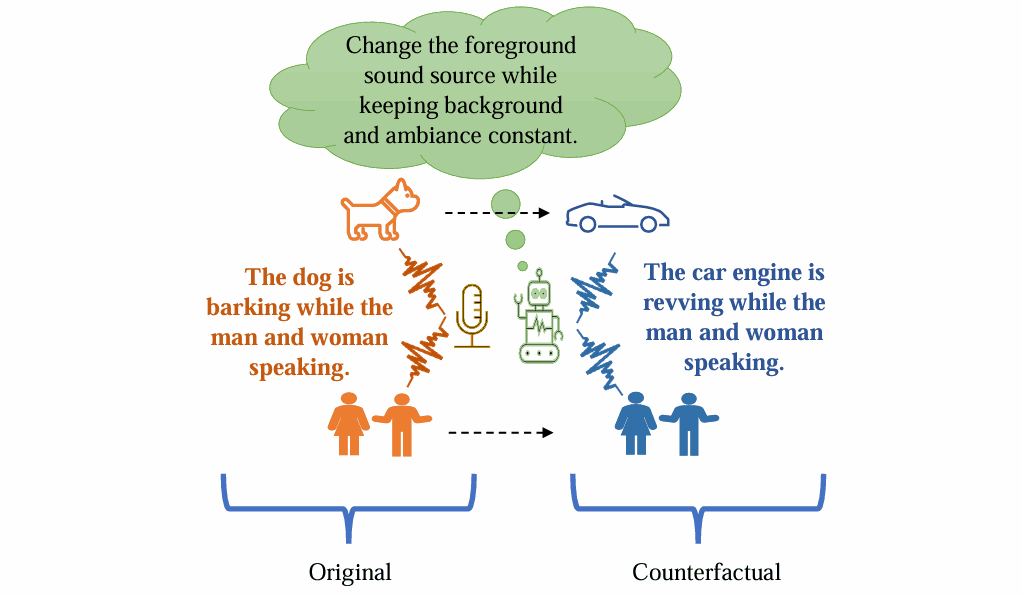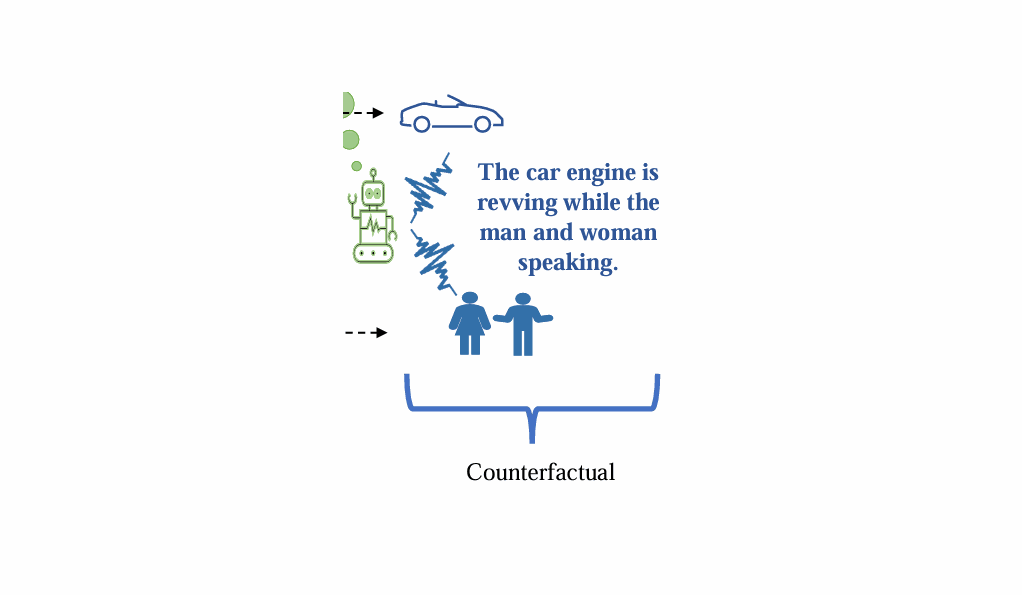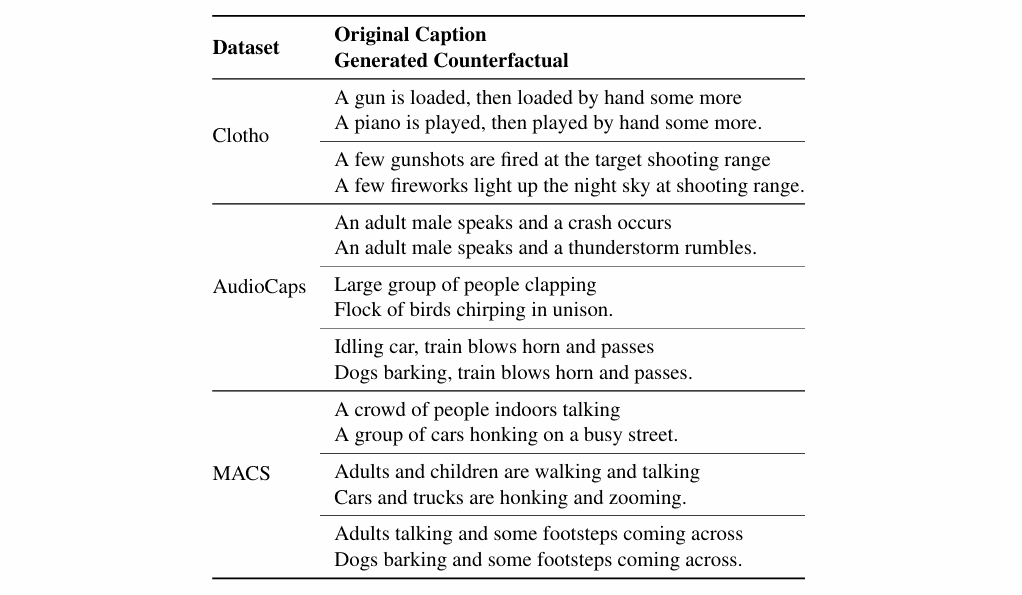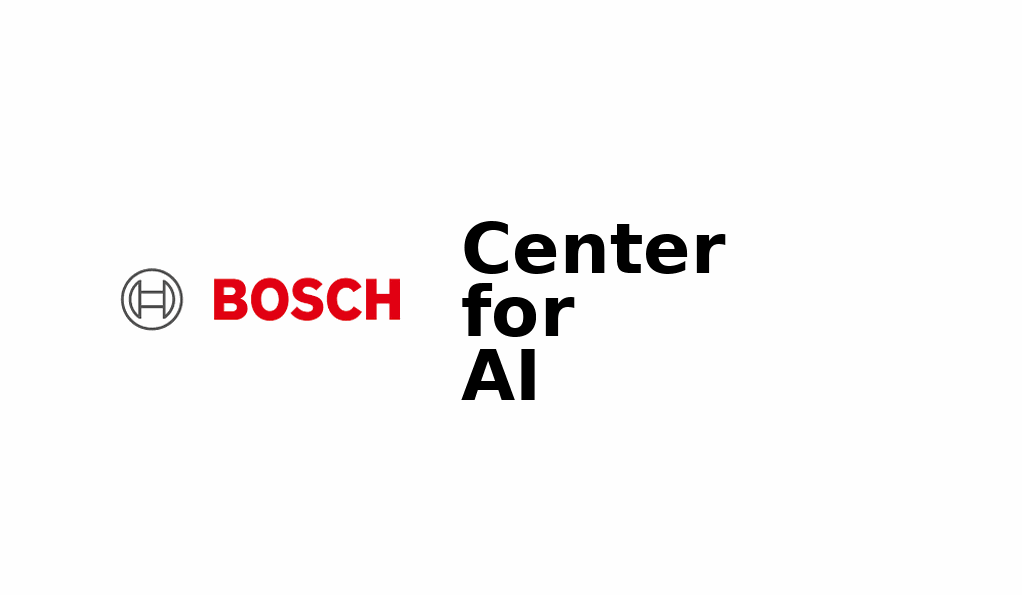
First counterfactual audio methods
ICASSP 2024 + US patent application US 2025/0124292 A1 (co-inventor, published Jan 2025)
ICASSP 2024 + US patent application US 2025/0124292 A1 (co-inventor, published Jan 2025)
PromptReverb
First text-to-spatial generation at 48kHz (ICASSP 2026)
First text-to-spatial generation at 48kHz (ICASSP 2026)
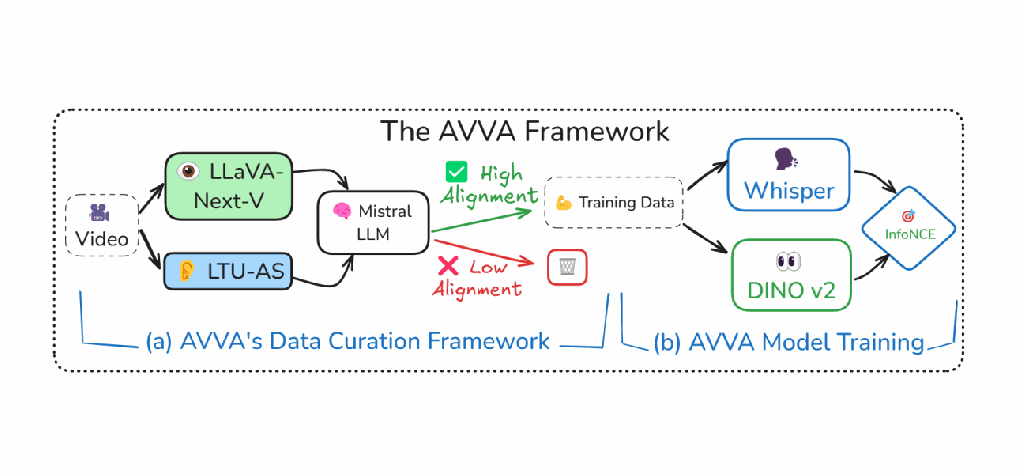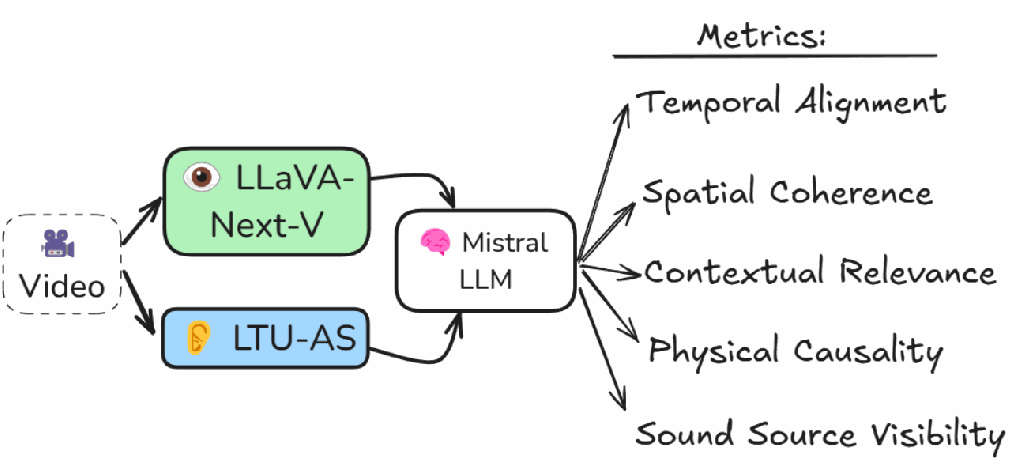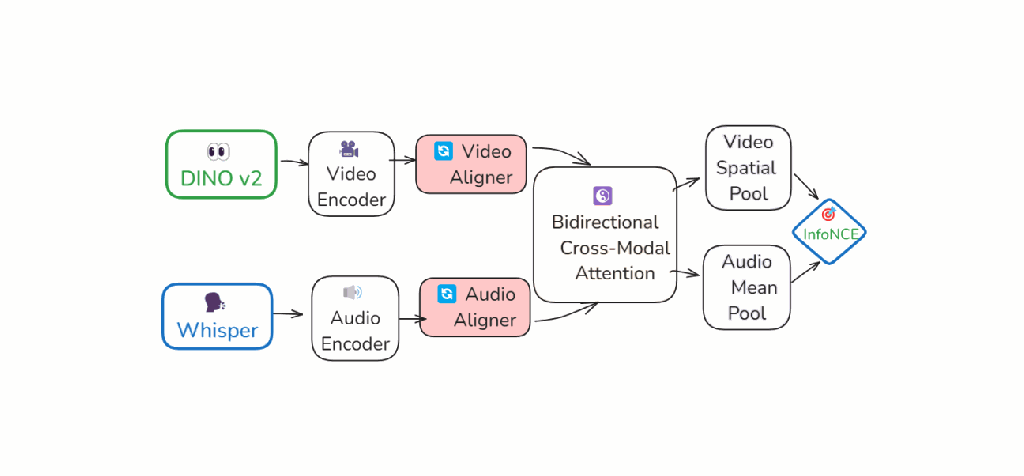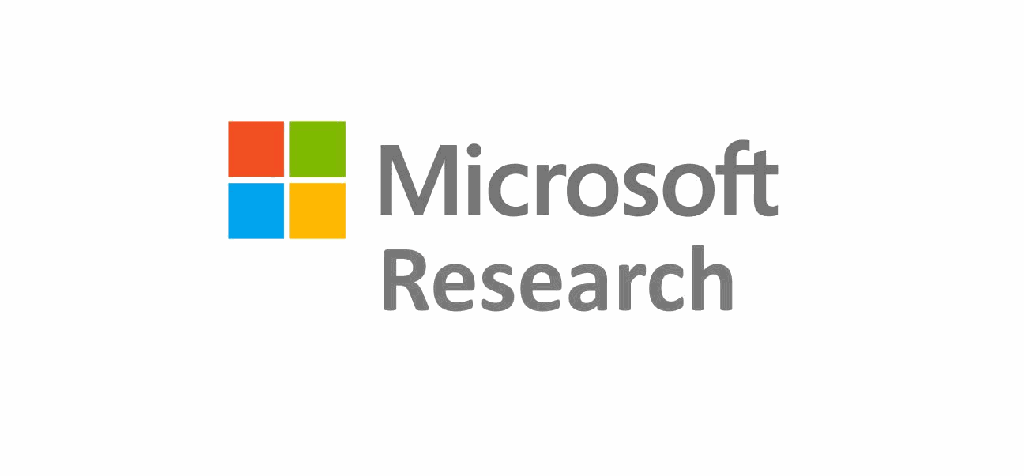
AVVA
Unified audiovisual foundation model with LLM curation (EUSIPCO 2025)
Unified audiovisual foundation model with LLM curation (EUSIPCO 2025)
Autonomous multimodal copilot
Real-time audiovisual AR demonstrations (DARPA)
Real-time audiovisual AR demonstrations (DARPA)
VERIFY benchmark
Stage-aware evaluation of multimodal reasoning fidelity (COLM 2026)
Stage-aware evaluation of multimodal reasoning fidelity (COLM 2026)
Video LMM Post-Training
Deep dive into video reasoning with large multimodal models
Deep dive into video reasoning with large multimodal models
AVE-2 Dataset
Open audiovisual benchmark for cross-modal event understanding
Open audiovisual benchmark for cross-modal event understanding
Recent News & Updates
08/2026
🏆 COLM 2026 acceptance: VERIFY, a 600-item visual reasoning benchmark with human-annotated reasoning paths and stage-aware evaluation
08/2026
📄 SPIE Medical Imaging 2027: four papers submitted on medical vision-language evaluation and causal inference methods
06/2026
📄 I²G released in the IEEE/CVF CVPR 2026 Workshop Proceedings: Generating Instructional Illustrations via Text-Conditioned Diffusion
05/2026
📄 ICASSP 2026 paper accepted as oral presentation: PromptReverb (Text-to-Spatial-Audio Generation at 48kHz)
02/2026
🏆 AAAI 2026 Best Demonstration Award Runner-up: Caption Anything in Video (Spatiotemporal Video Understanding and Multimodal Prompting)
12/2025
📄 NeurIPS 2025 paper accepted: MMPerspective (Multimodal LLM Reasoning, Video and Visual Perception)
09/2025
✅ Completed research internship at Smule AI (Spatial Audio Generation and Synthesis)
06/2025
🎵 Started research internship at Smule AI (Spatial Audio Generation and Immersive Computing)
03/2025
📊 Published VERIFY benchmark (Multimodal Reasoning Verification for Video and Vision LLMs)
10/2024
🎤 Presented at SANE 2024 at Google, Cambridge, MA (Audio Understanding, Video LLMs, and Spatial Audio)
10/2024
📄 ACM Multimedia 2024: EAGLE (Egocentric Video Understanding and Language Generation)
08/2024
💼 Research presentation at Microsoft Research (Audiovisual LLM, Video and Audio Understanding)
03/2024
📄 NAACL 2024: OSCaR (Video Object State Captioning, Autonomous Video Perception)
02/2024
📄 IEEE Transactions on Multimedia 2024: PW-VQA (Causal Visual Question Answering, Video Reasoning)
08/2023
🎯 Two ICCV 2023 papers accepted (Audiovisual Sound Separation and Autonomous AR Perception System)
04/2023
🏢 Started internship at Bosch Center for AI (Audio Language Models and Counterfactual Reasoning)
Publications
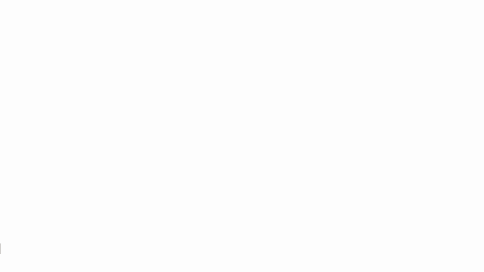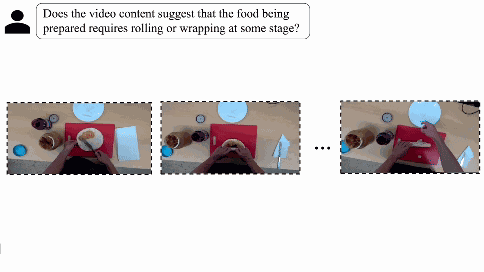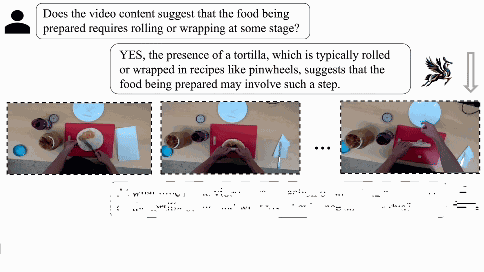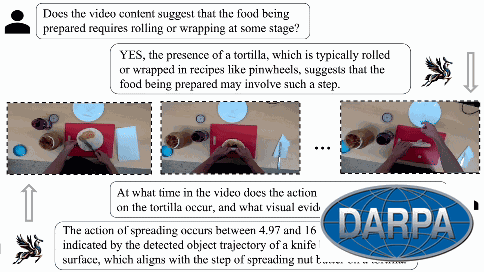
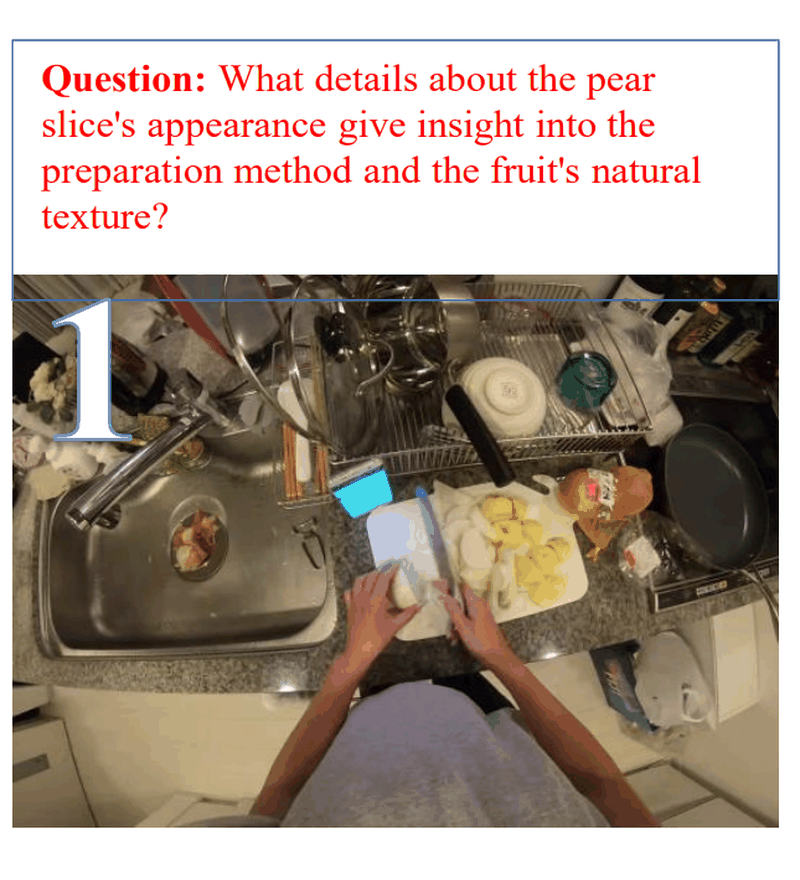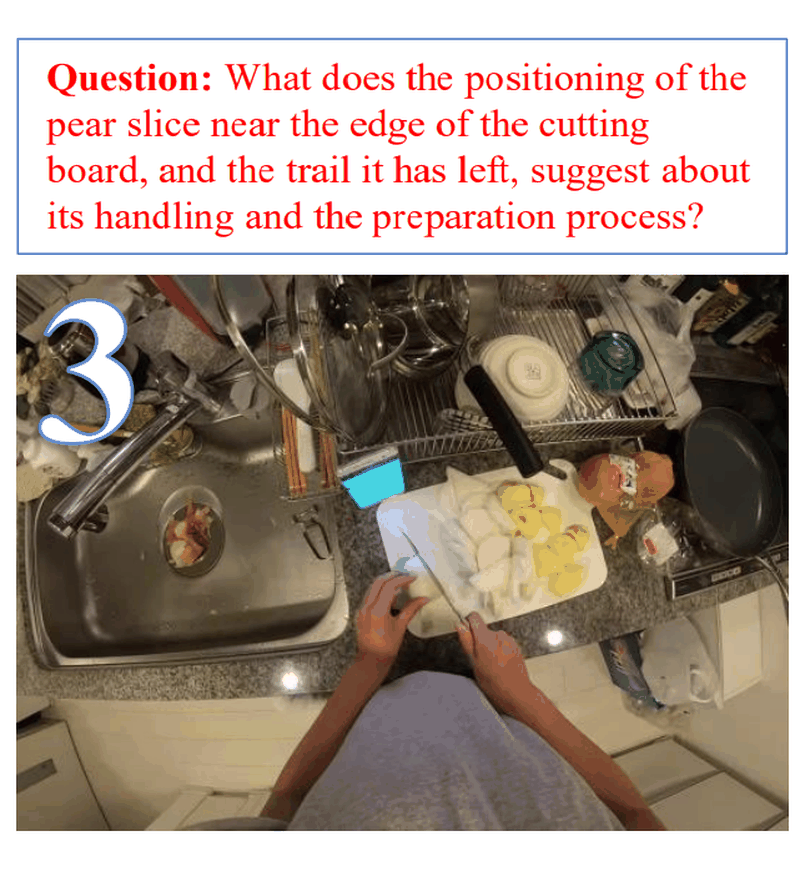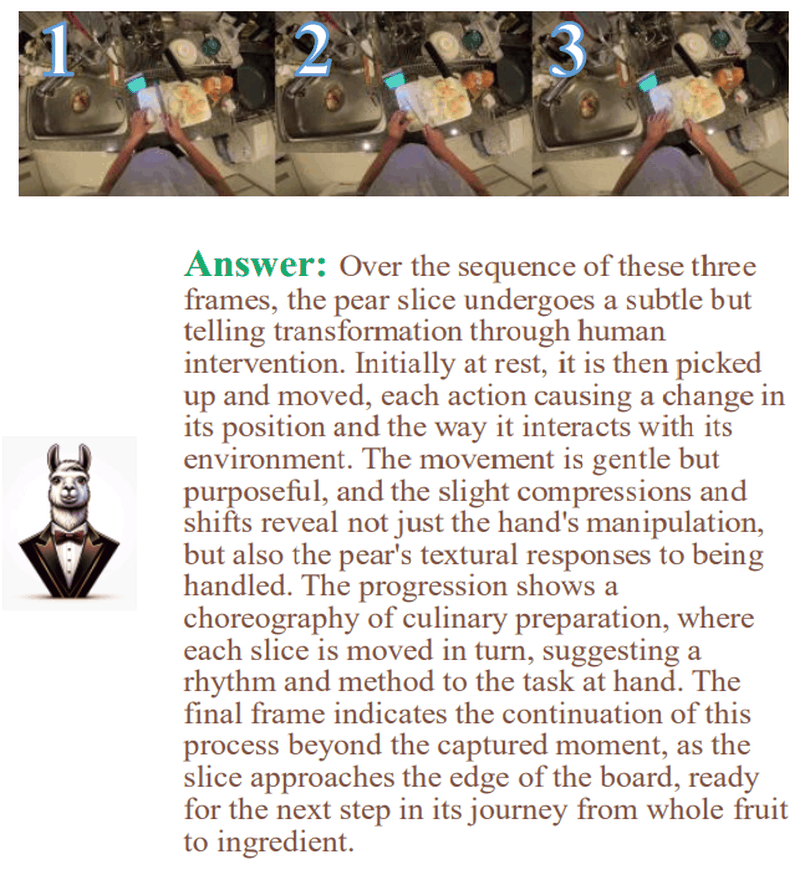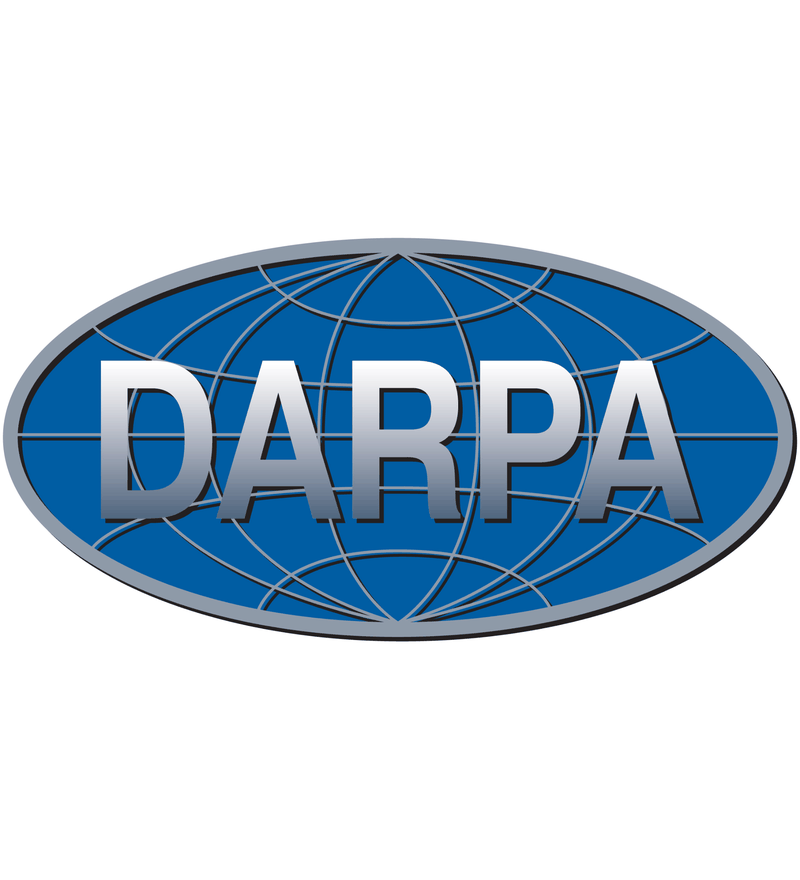
EAGLE: Egocentric AGgregated Language-video Engine
ACM International Conference on Multimedia (ACM MM) 2024
[Paper][DARPA PTG Demo]
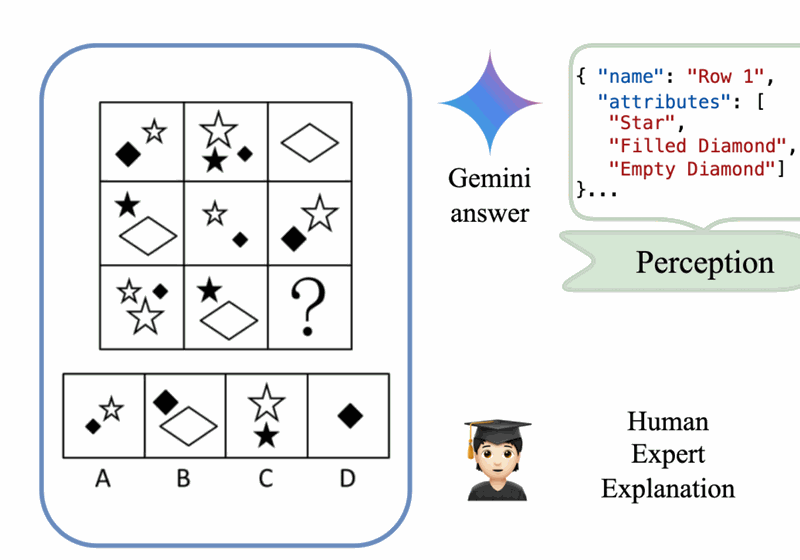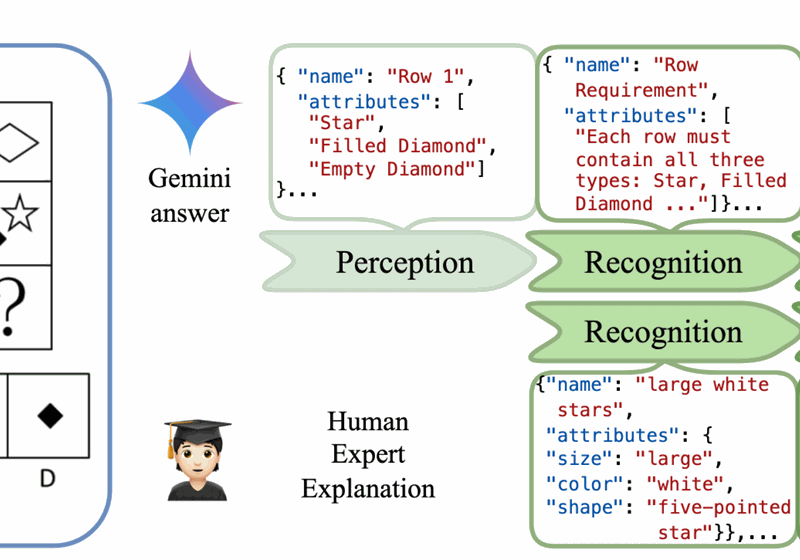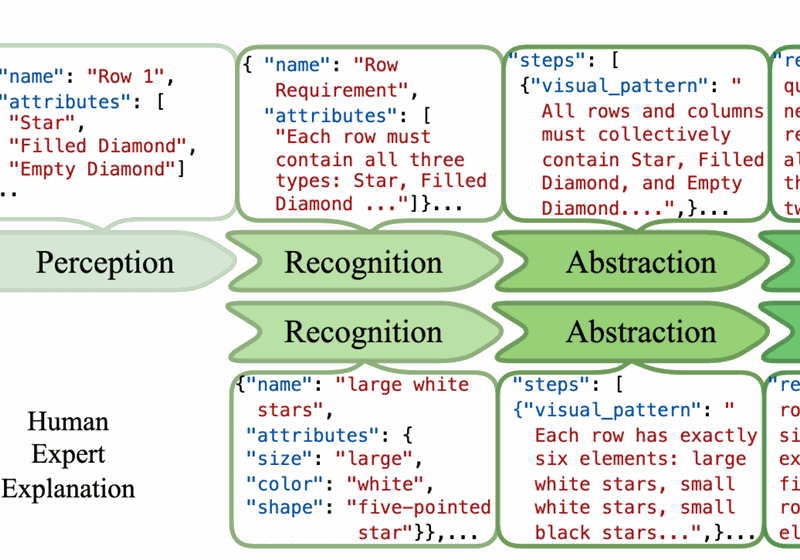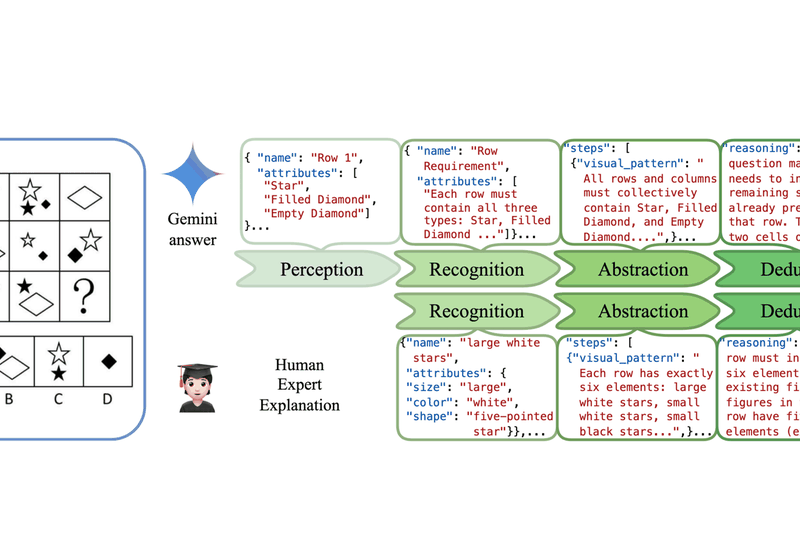
VERIFY: A Benchmark of Visual Explanation and Reasoning for Investigating Multimodal Reasoning Fidelity
Conference on Language Modeling (COLM) 2026
[Paper][Website][🤗 Hugging Face]

AVSA-Sep: Separating Invisible Sounds Toward Universal Audiovisual Scene-Aware Sound Separation
IEEE/CVF International Conference on Computer Vision (ICCV) 2023: ICCV AV4D Workshop
[Paper]
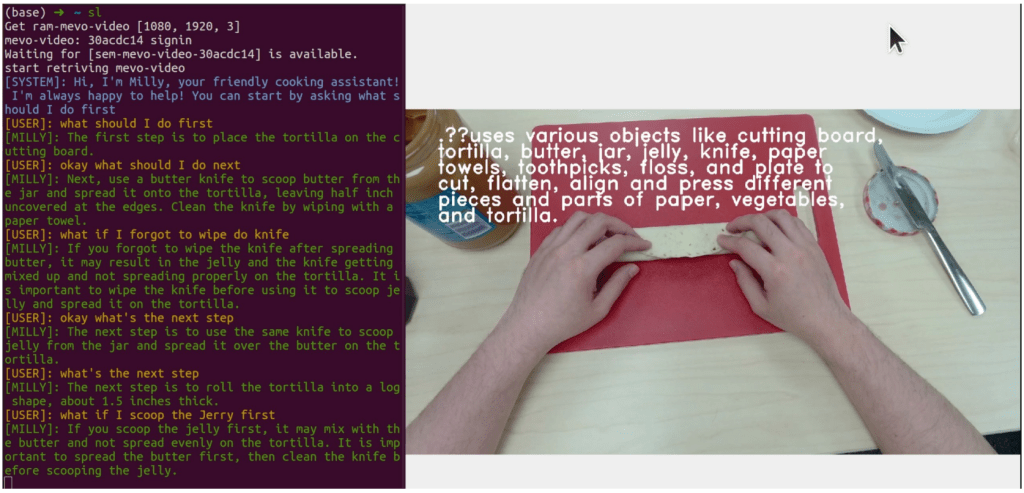
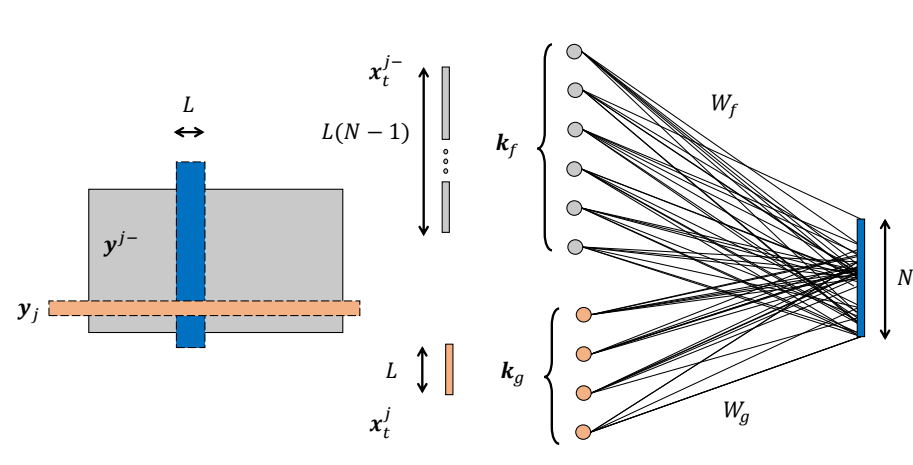
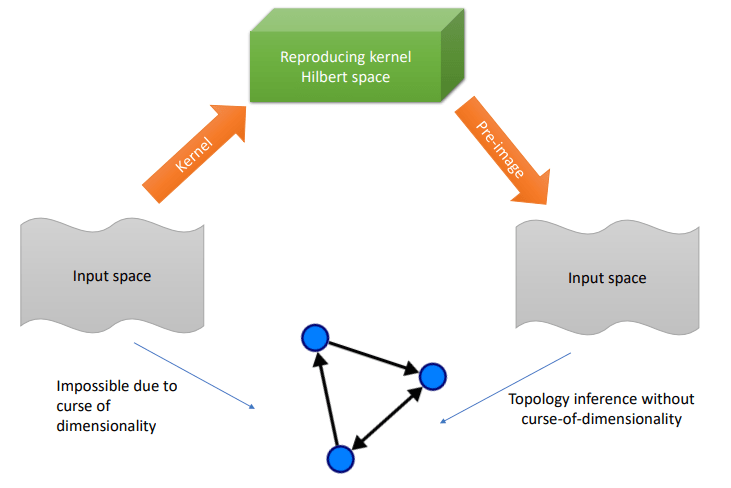
Leveraging Pre-Images to Discover Nonlinear Relationships in Multivariate Environments
European Signal Processing Conference (EUSIPCO) 2021
[Paper]

Personal Gallery